Anthony Cavin
Co-founder & CEO - Data, ML & Robotics Systems

Co-founder and CEO working on data pipelines, machine learning, and robotics systems. Focused on real-time data processing and turning complex data into production-ready intelligence.

View all authors

How to Store Vibration Sensor Data | ReductStore vs InfluxDB
· 10 min read
Anthony Cavin
Co-founder & CEO - Data, ML & Robotics Systems

Benchmark Results

In How to Store Vibration Sensor Data, we discuss the importance of efficiently storing both raw vibration data and pre-processed metrics, and the benefits of using time-series databases such as ReductStore. We explore best practices for setting up a time-series database and implementing data retention policies to effectively manage high-frequency sensor data.

We also see how to store vibration sensor values in 1-second chunks, each packaged as binary data, to optimize the storage process when dealing with high-frequency data such as vibration or acoustic measurements.

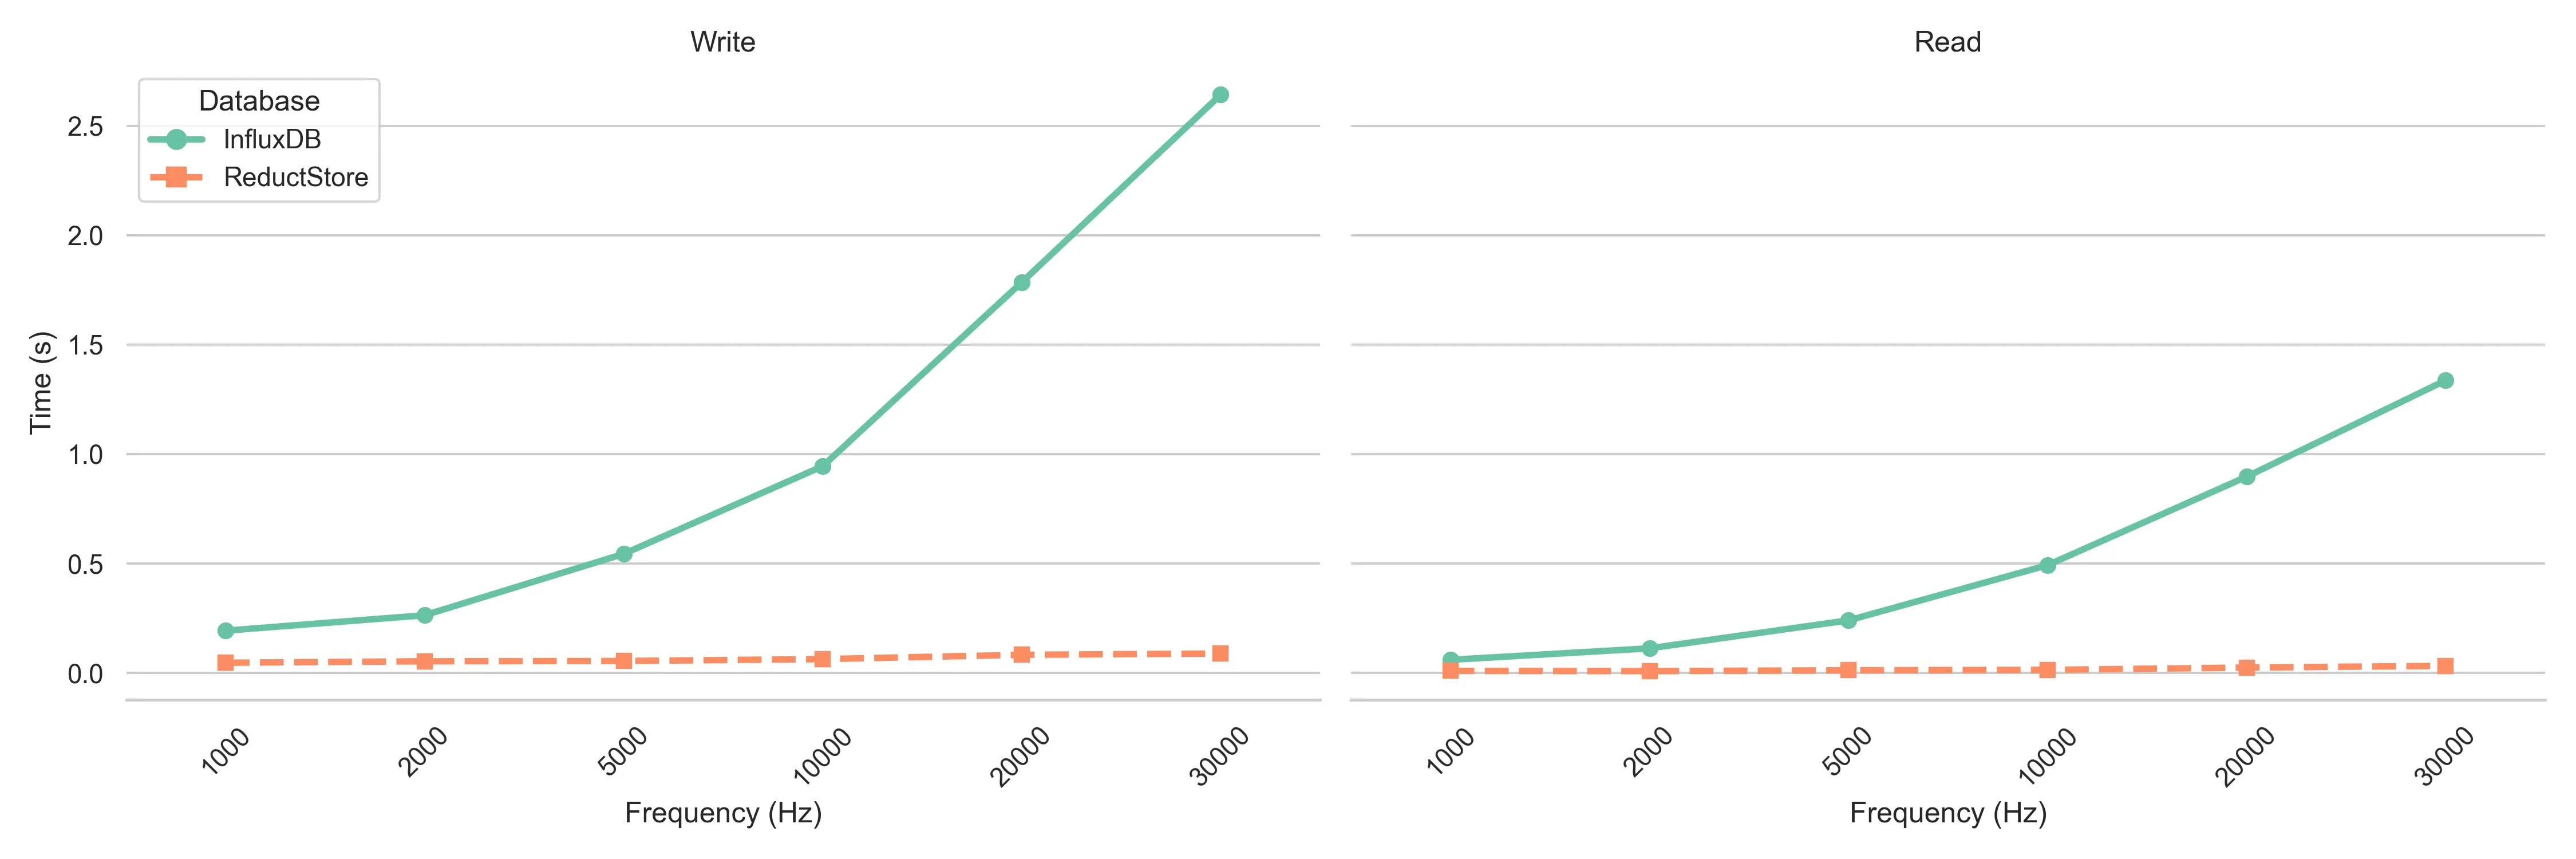
In this post, we compare ReductStore and InfluxDB in a real-world benchmark scenario, focusing on their write and read performance for high-frequency sensor data. We show how ReductStore's binary storage provides superior efficiency and scalability over InfluxDB when handling large volumes of unstructured time-series data.

The benchmark was run on an SSD drive, but results may vary depending on hardware configuration and database settings; to explore how it performs on your setup, you can run the benchmark yourself using the Reduct Vibration Example repository on GitHub.
Alternative to MongoDB for Blob Data

· 9 min read
Anthony Cavin
Co-founder & CEO - Data, ML & Robotics Systems

ReductStore vs MongoDB

In edge computing, managing time series blob data efficiently is critical for performance-sensitive applications. This blog post will compare ReductStore, a specialized time series database for unstructured data, and MongoDB, a widely-used NoSQL database.

Using Docker containers for straightforward setup, we'll examine the speed of each system. We'll go through setting up ReductStore buckets and preparing MongoDB collections, focusing on how to effectively store and access blob data for time series scenarios.

By conducting performance tests on binary data insertion and retrieval, we aim to provide insights into which system might best serve your application's needs.

For those interested in replicating our benchmarks or conducting their own evaluations, we've made our methods easily accessible through this repository.

How to Use Reductstore as a Data Sink for Kafka

· 8 min read
Anthony Cavin
Co-founder & CEO - Data, ML & Robotics Systems

In this guide, we will explore the process of storing Kafka messages that contain unstructured data into a time series database.

Apache Kafka is a distributed streaming platform capable of handling high throughput of data, while ReductStore is a databases for unstructured data optimized for storing and querying along time.

ReductStore allows to easily setup a data sink to store blob data for applications that need precise time-based querying or a robust system optimized for edge computing that can handle quotas and retention policies.

This guide builds upon an existing tutorial which provides detailed steps for integrating a simple architecture with these systems. To get started, revisit "Easy Guide to Integrating Kafka: Practical Solutions for Managing Blob Data" if you need help setting up the initial infrastructure.

You can also find the code for this tutorial in the kafka_to_reduct demo on GitHub.